这项研究解决什么问题
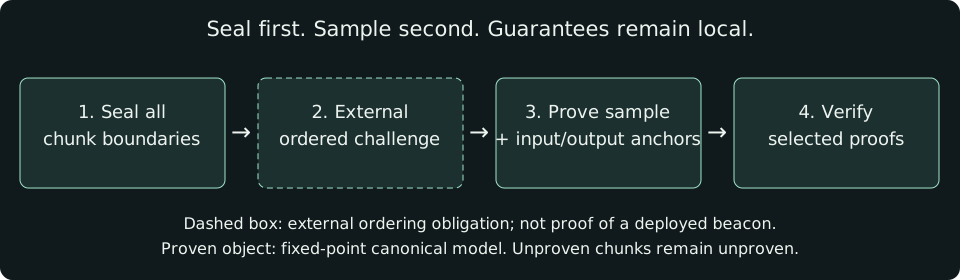
推理提供方掌握内部计算过程,用户通常只能看到答案。SLP 要求提供方先承诺各计算分块的边界激活,再由挑战决定需要证明的分块,并通过输入、输出锚点将轨迹绑定到请求。如果先看到抽样结果再修改轨迹,审查就会失去意义。
原型测量了抽样可以节省多少证明工作。在报告的 TinyLlama 轨迹中,证明 47 个分块中的 7 个,耗时为完整证明的 22.0%,证明体积为 6.8%。这是该实验的测量结果,不是通用提速承诺,也不是答案正确的概率。
请求打包用于分摊与权重相关的证明工作;70B 实验则展示了在 2 TB 内存 CPU 主机上使用磁盘权重与流式处理完成实验的实现路线。这些结果可用于研究成本和内存需求,不代表已部署服务的性能。论文中的模拟服务也必须与真实生产流量区分。
证明针对定点规范模型,保证只覆盖被证明的分块。在 70B 设置下,一个固定错误分块被抽中的概率为 3/161。所有测量使用测试参考串;仅依赖清单的挑战构造仍需要外部确定顺序的挑战来抵抗反复尝试。生产设计必须处理这些假设,不能将原型当成端到端验证。
阅读原始英文摘要
Verifying outsourced language-model inference requires a precisely identified computation and an audit whose cost a service can afford. We present Sampled Layerwise Proofs (SLP), a protocol and prototype that commits the boundary activations of every chunk of an inference trace, absorbs all commitments before any challenge is drawn, and then proves a verifier-selected subset of chunks together with the chunks that bind the prompt and the answer. Audit coverage becomes a runtime parameter over one set of commitments: on a TinyLlama-1.1B trace, proving seven of 47 chunks takes 22.0% of the time and 6.8% of the proof size of proving all 47. Because proof cost is dominated by weights rather than tokens, SLP packs concurrent requests into one trace under a block-diagonal causal mask and binds each request’s prompt and answer to its slot. Twelve packed requests are proved in 181.9 s, 6.5 times less than twelve separate proofs at the measured single-proof cost, and a simulated service proves twelve requests at 30.6 s per request with 0.6 s of verification each, rejecting a tampered answer. Disk-backed integer weights and streamed polynomial commitments let a single Llama-2-70B run complete on a 2 TB CPU host: 163 chunks sealed, five proved, a 4.34 MiB proof in 1,259 s, verified in 46.3 s without the weights. The proven object is a fixed-point canonical model; we trace a severe fidelity loss to the residual-stream bit width, repair it with an LLM-aware observer, and measure 84.8-84.9% argmax agreement with the floating-point reference over 334,705 WikiText-2 test positions. The limits are stated as precisely: guarantees cover proven chunks only, a fixed invalid chunk in the 70B setting is covered with probability 3/161, a manifest-only Fiat-Shamir schedule can be ground at 12.5 ms per attempt and needs an externally ordered challenge, and all measurements use a test reference string.
版本与使用说明
PDF 为 Youki Lim 与 Sam Yong 的 arXiv v1 原件,未经修改,采用 CC BY 4.0。本页解读与流程图为新增说明。早期 SLP PoC 报告是另一份材料,不应将两个版本的数字混用。 CC BY 4.0 · 早期 PoC 解读
引用原始论文
@misc{lim2026sealthensample,
  title = {Seal, Then Sample: Sampled Layerwise Proofs for Verifiable LLM Inference from GPT-2 to 70B},
  author = {Lim, Youki and Yong, Sam},
  year = {2026},
  eprint = {2609.27367},
  archivePrefix = {arXiv},
  primaryClass = {cs.CR},
  doi = {10.48550/arXiv.2609.27367},
  url = {https://arxiv.org/abs/2609.27367v1},
  note = {Version 1; submitted 23 September 2026}
}