What this work establishes
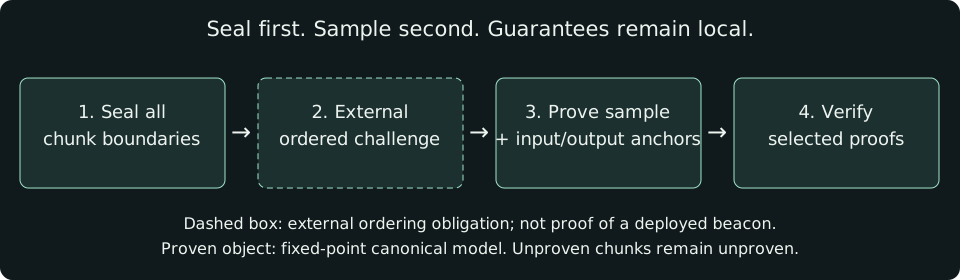
An inference provider knows the internal computation it ran; a customer normally sees only the answer. SLP makes the provider commit to chunk-boundary activations before an audit challenge selects chunks for proof. Prompt and answer anchors tie the sampled trace to the request. This ordering matters: allowing the provider to adapt the trace after learning the sample would undermine the audit.
The prototype evaluates how much proving work can be avoided by sampling. In the reported TinyLlama trace, proving seven of 47 chunks used 22.0% of full-proof time and 6.8% of full-proof size. These are measurements of that experiment, not a universal speed guarantee or a probability that an answer is correct.
Packing requests amortizes weight-related proving work. Separately, the 70B run demonstrates a disk-backed, streamed implementation on a 2 TB CPU host. These experiments help engineers investigate cost and memory requirements; neither constitutes a deployed service benchmark. The paper’s simulated service result must also be distinguished from production traffic.
The proof concerns a fixed-point canonical model and only the proven chunks. In the 70B setup a fixed invalid chunk has sampling coverage of 3/161. All measurements use a test reference string, and the manifest-only challenge construction needs an externally ordered challenge to resist grinding. A production design must address those assumptions rather than treating this prototype as end-to-end verification.
Read the original abstract
Verifying outsourced language-model inference requires a precisely identified computation and an audit whose cost a service can afford. We present Sampled Layerwise Proofs (SLP), a protocol and prototype that commits the boundary activations of every chunk of an inference trace, absorbs all commitments before any challenge is drawn, and then proves a verifier-selected subset of chunks together with the chunks that bind the prompt and the answer. Audit coverage becomes a runtime parameter over one set of commitments: on a TinyLlama-1.1B trace, proving seven of 47 chunks takes 22.0% of the time and 6.8% of the proof size of proving all 47. Because proof cost is dominated by weights rather than tokens, SLP packs concurrent requests into one trace under a block-diagonal causal mask and binds each request’s prompt and answer to its slot. Twelve packed requests are proved in 181.9 s, 6.5 times less than twelve separate proofs at the measured single-proof cost, and a simulated service proves twelve requests at 30.6 s per request with 0.6 s of verification each, rejecting a tampered answer. Disk-backed integer weights and streamed polynomial commitments let a single Llama-2-70B run complete on a 2 TB CPU host: 163 chunks sealed, five proved, a 4.34 MiB proof in 1,259 s, verified in 46.3 s without the weights. The proven object is a fixed-point canonical model; we trace a severe fidelity loss to the residual-stream bit width, repair it with an LLM-aware observer, and measure 84.8-84.9% argmax agreement with the floating-point reference over 334,705 WikiText-2 test positions. The limits are stated as precisely: guarantees cover proven chunks only, a fixed invalid chunk in the 70B setting is covered with probability 3/161, a manifest-only Fiat-Shamir schedule can be ground at 12.5 ms per attempt and needs an externally ordered challenge, and all measurements use a test reference string.
Version and reuse
The PDF is an unchanged copy of arXiv v1 by Youki Lim and Sam Yong, licensed CC BY 4.0. The explanation and diagram on this page are editorial additions. The earlier SLP PoC report is a separate artifact; do not mix its numbers with this version. CC BY 4.0 · Earlier PoC overview
Cite the original paper
@misc{lim2026sealthensample,
  title = {Seal, Then Sample: Sampled Layerwise Proofs for Verifiable LLM Inference from GPT-2 to 70B},
  author = {Lim, Youki and Yong, Sam},
  year = {2026},
  eprint = {2609.27367},
  archivePrefix = {arXiv},
  primaryClass = {cs.CR},
  doi = {10.48550/arXiv.2609.27367},
  url = {https://arxiv.org/abs/2609.27367v1},
  note = {Version 1; submitted 23 September 2026}
}